
I saw this post (via Dave Winer) about issues with the ability of feed readers to read feeds from websites hosted by or using Cloudflare. I ran into this problem in trying to access feeds from the Seattle Times website (eventually had to use Playwright to act as a web browser to download the files). This is especially sad for the Seattle Times, since it runs on WordPress. However, it is good to see this confirmation of this problem (interestingly, it was posted in 2024).
Feeds
There are 125 posts filed in Feeds (this is page 1 of 13).
More gripes about RSS feeds from newspaper websites
I am continuing work on my Feed News Archive project, adding feeds from US newspaper websites. There is a combination of sites that do not offer feeds, sites with difficult ways to access feeds, some WordPress VIP sites that block access to their feeds (?!) and one (Seattle Times) that seems to only allow access to feeds via a web browser – ugh! To get around this, I am looking into news sitemaps as a way to create feeds for sites, then subscribe to those feeds. It’s more work than I want to do, but I am pressing on.
Other examples of inbound/outbound RSS support
Dave Winer pointed to Ricardo Mendes from his linkblog on July 10 with the title “Inbound and Outbound RSS”. I took a look at the Mendes post, he describes using Indiekit and plugins to both read and write posts. I think this is very similar to my minimal blogging tool MyStatusTool. In the Mendez setup, it sounds like he is also reading feeds that do not include rssCloud support.
Mendez also mentions work by Aaron Parecki on the Monacle social feed reader/writer. This tool used the Micropub and Microsub specs for publishing and subscribing. The above link is from 2016, so you can see that this predates both the MyStatusTool and rss.chat tools.
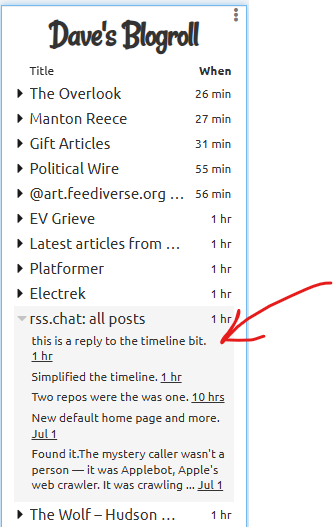
rss.chat makes its premiere
The rss.chat service was publicly introduced today. At this time, it appears to be restricted. Hopefully, the full service will be available soon for everyone.
Looks like Dave Winer’s new RSS thing is out
What are the attributes of a “social platform”?
On June 28, 2026, Dave Winer put out a call for social web app developers to work with him if they are including inbound and outbound RSS in their apps. Manton Reece from Micro.blog referenced this in a post on Micro.blog, and had this statement: “I’m actually not aware of any social platforms that support inbound RSS except Micro.blog. It would be great to have more.”. Dave Winer then responded on Micro.blog as follows (partial quote):
I want a world of social platforms that support inbound RSS
Those two posts caught my eye, specifically the word “platform”. Why did they choose the word “platform”? That made me wonder – is this really a call for “centralized” services like Bluesky/Mastodon to add inbound RSS (to allow users to post within these services as “first class citizens” (as if they were posting within official apps for Bluesky/Mastodon))? In earlier comments on this topic, I wrote:
I have addressed this second objection before, stating “What is in it for the “other people’s software developers to add inbound and outbound RSS support”? My answer is – nothing – no users are demanding this – no users are clamoring for a RSS-based “social network” that can communicate as a peer with other social network software.
I had developed a web app in 2023 called MyStatusTool, and this app allows users to follow RSS feeds that support rssCloud (inbound RSS) and allows the user to create their own posts with a feed (outbound RSS). However, I had not thought about the following/display of other RSS feeds as “inbound RSS” until now.
I created this app because back in 2022, Dave Winer kept talking about creating an app that could do this, but he did not actually do anything about it, so I decided to do it! The one feature this app does not have is support for replies/following threads, which “platforms” like Bluesky, Mastodon, and Micro.blog support. Perhaps that is a key “attribute” of a “social platform”….
From recent posts, I am aware that Dave Winer is “working on something” with RSS and rssCloud to create some chat application. Hope he releases it soon! Hope it has inbound and outbound RSS!
Disappointing results for RSS feeds from US newspapers
As part of my News Archive project, I am trying to add feeds from one major US newspaper per day. As a start, I used this Wikipedia page (which has a list of the top 10 US papers by circulation). Only 7 of 10 papers had feeds (Chicago Tribune, USA Today, and Newsday did not have feeds). Some of them have feeds by default because their sites are built using WordPress (there were no links to those feeds, but by going to sections and adding “/feed/” to the end of the URLs – voila! Feeds!
Another interesting possibility is the existence of sitemaps in XML format. It appears this is being done so that Google can index content. I used Claude to create a script for creating a RSS feed from a sitemap file (see Github gist here). I am going to start using this for sites that do not provide feeds.
I appreciate blogs and RSS
I use River5 to read feeds (see here). When I read feeds on my phone, I open tabs with posts I want to read/keep. At this writing, the number of tabs is 81. Why is the number so high? Because I read a lot of feeds, and these feeds are from blogs, not news websites. I check news websites, but I do not subscribe to many feeds from news websites (too much flow there).
I appreciate blogs because I would not be able to get the wide variety of information/viewpoints if I only subscribed to mainstream media. Also, I can drop feeds if they no longer are of interest. Finally. almost all blogs have feeds to which I can subscribe. Interestingly (or perhaps sadly), many mainstream media newspapers/news websites do not provide feeds – grrr!
I want to send out a big “Thank you!” to Dave Winer for his work in making blogging and feed reading available to all, and for developing and promoting the use of RSS to share the work of our blogs with the world.
Dave Winer posted on Sunday: “Right now we could put a twitter-like product there that you can set up in a few minutes, run it yourself, and or join one that’s run by a friend.” Is this what he is talking about?
Here’s a task where AI did a poor job
In a previous post, I mentioned that I asked Claude to collect RSS feeds for US newspapers. Here was the prompt:
Create a list of RSS feeds and save them using the following steps:
* Review all of the newspapers linked from this page (https://en.wikipedia.org/wiki/List_of_newspapers_in_the_United_States ), identify if they have a website, and make a list of the RSS feeds available from the website.
* Identify which newspapers do not have RSS feeds
* Identify which newspapers do not have websites
* Create a OPML subscription list of all RSS feeds identified and save this file to C:\Users\sylve\Documents\Claude_Projects\News_Archive
* Create a text file that lists the newspapers that do not have RSS feeds and save this file to C:\Users\sylve\Documents\Claude_Projects\News_Archive
* Create a text file that lists the newspapers that do not have websites and save this file to C:\Users\sylve\Documents\Claude_Projects\News_Archive
* Add the OPML and text files created to a new repository in my Gitlab account called news-archive
The result of this prompt was an OPML file with 386 feed URLs, but only 22 of them had any items. I looked at the first 5 feeds, and saw that Claude had taken the root URL of a site and added “/rss/” to the URL. There was nothing there. Why did Claude do that? Why did it not search on the site to find a valid feed, and if there was none, to add it to the list of newspapers that do not have feeds? If anyone has any insight into this, I would love to hear it.